上海大学学报(自然科学版) ›› 2023, Vol. 29 ›› Issue (1): 24-40.doi: 10.12066/j.issn.1007-2861.2332
朱永华, 冯天宇, 张美贤, 张文俊( )
收稿日期:2021-03-20
出版日期:2023-02-28
发布日期:2023-03-28
通讯作者:
张文俊
E-mail:wjzhang@shu.edu.cn
作者简介:张文俊(1959—), 男, 教授, 博士生导师, 博士, 研究方向为数字媒体技术与应用、数字新媒体、网络通信技术及计算电磁学等. E-mail: wjzhang@shu.edu.cn
ZHU Yonghua, FENG Tianyu, ZHANG Meixian, ZHANG Wenjun()
Received:2021-03-20
Online:2023-02-28
Published:2023-03-28
Contact:
ZHANG Wenjun
E-mail:wjzhang@shu.edu.cn
摘要:
提出了一种新颖的语音情感识别结构, 从声音文件中提取梅尔频率倒谱系数(Mel-scale frequency cepstral coefficients, MFCCs)、 线性预测倒谱系数(linear predictive cepstral coefficients, LPCCs)、色度图、梅尔尺度频谱图、Tonnetz 表示和频谱对比度特征, 并将其作为一维卷积神经网络(convolutional neural network, CNN) 的输入. 构建由一维卷积层、Dropout 层、批标准化层、权重池化层、全连接层和激活层组成的网络, 并使用Ryerson 情感说话/歌唱视听(Ryerson audio-visual database of emotional speech and song, RAVDESS) 数据集、柏林语音数据集(Berlin emotional database, EMO-DB)、交互式情绪二元运动捕捉 (interactive emotional dyadic motion capture, IEMOCAP) 数据集这3 个数据集的样本来识别情感. 为提高分类精度, 利用增量方法修改初始模型. 为解决网络自动处理情感信息在话语中分布不均匀的问题, 采用了一种基于注意力机制的加权池方法来生成更有效的话语级表征. 实验结果显示: 该模型在RAVDESS 和IEMOCAP 数据集上的性能都优于已有的方法; 对于EMO-DB, 该模型仅次于一种基线方法, 但其在通用性、简单性和适用性方面都具有优势.
中图分类号:
朱永华, 冯天宇, 张美贤, 张文俊. 基于增量方法的卷积语音情感识别网络[J]. 上海大学学报(自然科学版), 2023, 29(1): 24-40.
ZHU Yonghua, FENG Tianyu, ZHANG Meixian, ZHANG Wenjun. Convolutional speech emotion recognition network based on incremental method[J]. Journal of Shanghai University(Natural Science Edition), 2023, 29(1): 24-40.

图1
本工作提出的初始模型"

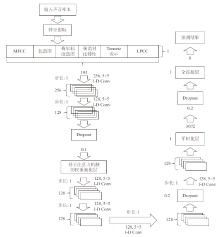
图2
RAVDESS 测试模型"

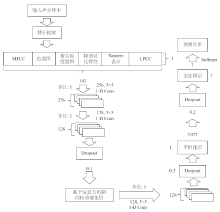
图3
模型A"


图4
模型B"

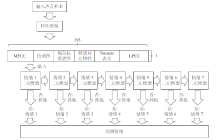
图5
模型C"

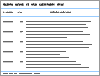
表1
模型C 中使用7 个二进制分类器的分类准确率"
 |
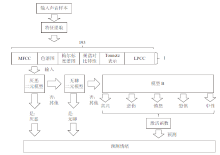
图6
模型D"

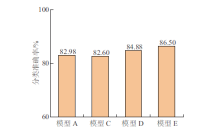
图7
本工作提出的不同模型针对EMO-DB 的分类精度对比"


图8
不同模型针对RAVDESS 数据集的分类精度对比"
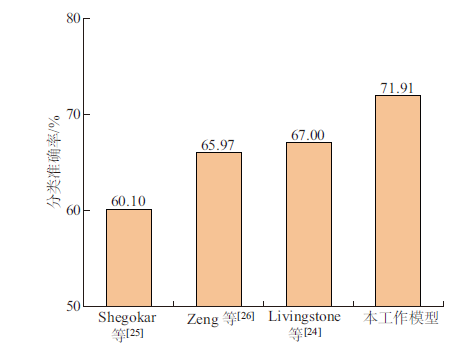
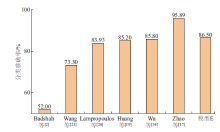
图9
不同模型针对EMO-DB 的分类精度对比"
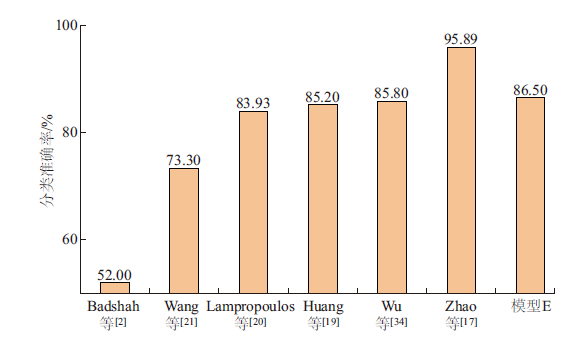

图10
不同模型针对520 个样本的EMO-DB 的分类精度对比"

图11
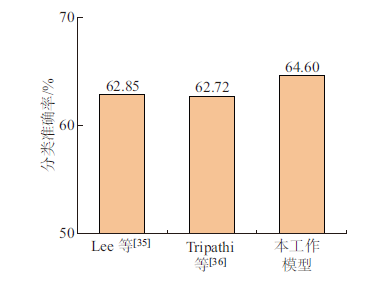
不同模型针对IEMOCAP 数据集的分类精度对比"
| [1] | Han I T K, Yu D. Speech emotion recognition using deep neural network and extreme learning machine[C]// Proceedings of the Interspeech. 2014: 223-227. |
| [2] | Badshah A M, Ahmad J, Rahim N, et al. Speech emotion recognition from spectrograms with deep convolutional neural network[C]// 2017 International Conference on Platform Technology and Service, IEEE. 2017: 1-5. |
| [3] | Mittal S, Agarwal S, Nigam M J. Real time multiple face recognition: a deep learning approach[C]// Proceedings of the 2018 International Conference on Digital Medicine and Image Processing, ACM. 2018: 70-76. |
| [4] | Bae H S, Lee H J, Lee S G. Voice recognition based on adaptive mfcc and deep learning[C]// 2016 IEEE 11th Conference on Industrial Electronics and Applications. 2016: 1542-1546. |
| [5] | He K, Zhang X, Ren S, et al. Deep residual learning for image recognition[C]// Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition. 2016: 770-778. |
| [6] | Huang K Y, Wu C H, Hong Q B, et al. Speech emotion recognition using deep neural network considering verbal and nonverbal speech sounds[C]// 2019 IEEE International Conference on Acoustics, Speech and Signal Processing. 2019: 5866-5870. |
| [7] | Lim W, Jang D, Lee T. Speech emotion recognition using convolutional and recurrent neural networks[C]// Signal and Information Processing Association Annual Summit and Conference, IEEE. 2016: 1-4. |
| [8] | Trigeorgis G, Ringeval F, Brueckner R, et al. Adieu features? End-to-end speech emotion recognition using a deep convolutional recurrent network[C]// 2016 IEEE International Conference on Acoustics, Speech and Signal Processing. 2016: 5200-5204. |
| [9] | Mirsamadi S, Barsoum E, Zhang C. Automatic speech emotion recognition using recurrent neural networks with local attention[C]// 2017 IEEE International Conference on Acoustics, Speech and Signal Processing. 2017: 2227-2231. |
| [10] | Xie Y, Liang R, Liang Z, et al. Speech emotion classification using attention-based LSTM[J]. IEEE-ACM Transactions on Audio Speech and Language Processing, 2017, 27 (11): 1675-1685. |
| [11] | Tarantino L, Garner P N, Lazaridis A. Self-attention for speech emotion recognition[C]// Proceedings of the Interspeech. 2019: 2578-2582. |
| [12] | Li R, Wu Z, Jia J, et al. Towards discriminative representation learning for speech emotion recognition[C]// Proceedings of the 28th International Joint Conference on Artificial Intelligence. 2019: 5060-5066. |
| [13] | 韩文静, 李海峰, 阮华斌, 等. 语音情感识别研究进展综述[J]. 软件学报, 2014, 25(1): 37-50. |
| [14] | 刘振焘, 徐建平, 吴敏, 等. 语音情感特征提取及其降维方法综述[J]. 计算机学报, 2018, 41(12): 2833-2851. |
| [15] | Niu Y F, Zou D S, Niu Y D, et al. Improvement on speech emotion recognition based on deep convolutional neural networks[C]// Proceedings of the 2018 International Conference on Computing and Artificial Intelligence. 2018: 13-18. |
| [16] | Burkhardt F, Paeschke A, Rolfes M, et al. A database of german emotional speech[C]// Ninth European Conference on Speech Communication and Technology. 2005: 1517-1520. |
| [17] | Zhao J, Mao X, Chen L. Speech emotion recognition using deep 1D & 2D CNN LSTM networks[J]. Biomedical Signal Processing and Control, 2019, 47: 312-323. |
| [18] | Demircan S, Kahramanli H. Application of fuzzy C-means clustering algorithm to spectral features for emotion classification from speech[J]. Neural Computing & Applications, 2018, 29: 59-66. |
| [19] | Huang Z, Dong M, Mao Q, et al. Speech emotion recognition using CNN[C]// Proceedings of the 22nd ACM International Conference on Multimedia. 2014: 801-804. |
| [20] | Lampropoulos A S, Tsihrintzis G A. Evaluation of MPEG-7 descriptors for speech emotional recognition[C]// 2012 Eighth International Conference on Intelligent Information Hiding and Multimedia Signal Processing, IEEE. 2012: 98-101. |
| [21] | Wang K, An N, Li B N, et al. Speech emotion recognition using fourier parameters[J]. IEEE Transactions on Affective Computing, 2015, 6: 69-75. |
| [22] | Chatziagapi A, Paraskevopoulos G, Sgouropoulos D, et al. Data augmentation using gans for speech emotion recognition[C]// Proceedings of the Interspeech. 2019: 171-175. |
| [23] | Yoon S, Byun S, Jung K. Multimodal speech emotion recognition using audio and text[C]// 2018 IEEE Spoken Language Technology Workshop. 2018: 112-118. |
| [24] | Livingstone S R, Russo F A. The Ryerson audio-visual database of emotional speech and song (RAVDESS): a dynamic, multimodal set of facial and vocal expressions in North American English[J]. PLoS One, 2018, 13: e0196391. |
| [25] | Shegokar P, Sircar P. Continuous wavelet transform based speech emotion recognition[C]// 2016 10th International Conference on Signal Processing and Communication Systems, IEEE. 2016: 1-8. |
| [26] | Zeng Y N, Mao H, Peng D Z, et al. Spectrogram based multi-task audio classification[J]. Multimedia Tools and Applications, 2019, 78: 3705-3722. |
| [27] | Popova A S, Rassadin A G, Ponomarenko A. Emotion recognition in sound[C]// International Conference on Neuroinformatics. 2017: 117-124. |
| [28] | McFee B, Raffel C, Liang D, et al. Librosa: audio and music signal analysis in python[C]// Proceedings of the 14th Python in Science Conference. 2015: 18-25. |
| [29] | Stevens S S, Volkmann J, Newman E B. A scale for the measurement of the psychological magnitude pitch[J]. Journal of the Acoustical Society of America, 1937, 8: 185-190. |
| [30] | Beigi H. Fundamentals of speaker recognition[M]. New York: Springer Science and Business Media Inc, 2011. |
| [31] | Jiang D N, Lu L, Zhang H J, et al. Music type classification by spectral contrast feature[C]// 2002 IEEE International Conference on Multimedia and Expo. 2002: 113-116. |
| [32] | Harte C, Sandler M, Gasser M. Detecting harmonic change in musical audio[C]// Proceedings of the 1st ACM Workshop on Audio and Music Computing Multimedia. 2006: 21-26. |
| [33] | Busso C, Bulut M, Lee C C, et al. IEMOCAP: interactive emotional dyadic motion capture database[J]. Language Resources and Evaluation, 2008, 42: 335. |
| [34] | Wu S, Falk T H, Chan W Y. Automatic speech emotion recognition using modulation spectral features[J]. Speech Communication, 2011, 53: 768-785. |
| [35] | Lee J, Tashev I. High-level feature representation using recurrent neural network for speech emotion recognition[C]// Sixteenth Annual Conference of the International Speech Communication Association. 2015: 1537-1540. |
| [36] | Tripathi S, Beigi H. Multi-modal emotion recognition on IEMOCAP dataset using deep learning[J]. CoRRabs, 2018(4): 05788. |
| [37] | Chen M, He X, Yang J, et al. 3-D convolutional recurrent neural networks with attention model for speech emotion recognition[J]. IEEE Signal Processing Letters, 2018, 25: 1440-1444. |
| [38] | Kim Y, Lee H, Provost E M. Deep learning for robust feature generation in audiovisual emotion recognition[C]// 2013 IEEE International Conference on Acoustics, Speech and Signal Processing. 2013: 3687-3691. |
| [39] | Lakomkin E, Weber C, Magg S, et al. Reusing neural speech representations for auditory emotion recognition[C]// The 8th International Joint Conference on Natural Language Processing. 2018. |
| [1] | 赵亚宁, 严利民. 基于生成对抗网络的图像鲁棒水印改进模型[J]. 上海大学学报(自然科学版), 2026, 32(2): 226-239. |
| [2] | 姜天豪, 王瑞. 基于多头注意力时空图卷积网络的交通事故预测[J]. 上海大学学报(自然科学版), 2025, 31(4): 678-690. |
| [3] | 韩大专, 张金艺, 姜玉稀. 面向数字孪生的深层特征融合低照度图像去雨线[J]. 上海大学学报(自然科学版), 2025, 31(3): 543-560. |
| [4] | 杨英杰, 王永芳, 张涵. 基于注意力和反馈机制的 HDR 视频重建[J]. 上海大学学报(自然科学版), 2023, 29(1): 56-67. |
| [5] | 陈茜, 武星. 结合上下文词汇匹配和图卷积的材料数据命名实体识别[J]. 上海大学学报(自然科学版), 2022, 28(3): 372-385. |
| [6] | 李成范, 赵俊娟. 面向遥感图像的小样本目标检测改进算法研究[J]. 上海大学学报(自然科学版), 2022, 28(2): 314-323. |
| [7] | 邢毅雪, 朱永华, 高海燕, 周金, 张克. 基于注意力机制的远程监督实体关系抽取[J]. 上海大学学报(自然科学版), 2021, 27(5): 983-992. |
| [8] | 季忠祥, 吴悦. 基于组合神经网络的中文事件抽取[J]. 上海大学学报(自然科学版), 2021, 27(3): 535-543. |
| [9] | 黄嘉宝, 朱永华, 周霁婷, 高文靖. 基于卷积神经网络的多肉植物细粒度图像分类[J]. 上海大学学报(自然科学版), 2020, 26(2): 283-291. |
| [10] | 周敬一, 郭燕, 丁友东. 基于深度学习的中文影评情感分析[J]. 上海大学学报(自然科学版), 2018, 24(5): 703-712. |
| [11] | 冉鹏, 王灵, 李昕, 刘鹏伟. 改进Softmax分类器的深度卷积神经网络及其在人脸识别中的应用[J]. 上海大学学报(自然科学版), 2018, 24(3): 352-366. |
| [12] | 刘惠彬, 陈强, 吴飞, 赵毅. 基于卷积神经网络的固定群体中目标人物分类[J]. 上海大学学报(自然科学版), 2017, 23(6): 874-. |
| 阅读次数 | ||||||
|
全文 |
|
|||||
|
摘要 |
|
|||||

